Claude Opus 5.5 is Anthropic's new-generation flagship model released in September 2026, officially positioned for "long-running agentic coding and knowledge work." It is the first model in the Claude 5.5 family, and it performs strongly across professional evaluations. Improved communication is a key focus of this upgrade. Anthropic says Opus 5.5's output is "more like a good colleague" — leading with information, reducing jargon, and following the writing rules users provide more strictly. Customer feedback supports this: one tester said design specification documents were nearly usable without modification, and the model's rewritten prompts were even preferred over the original author's own version. On safety, Anthropic says Opus 5.5 achieved its best results to date in automated behavior audits, covering nearly 2,000 simulated scenarios, with improvements in both resisting prompt injection and reducing hard-boundary breaches.
AI InterfaceYou Only Need
Faster, smarter, larger AI models at unbeatable value

Covers Multimodal, Text, Image, Video & More
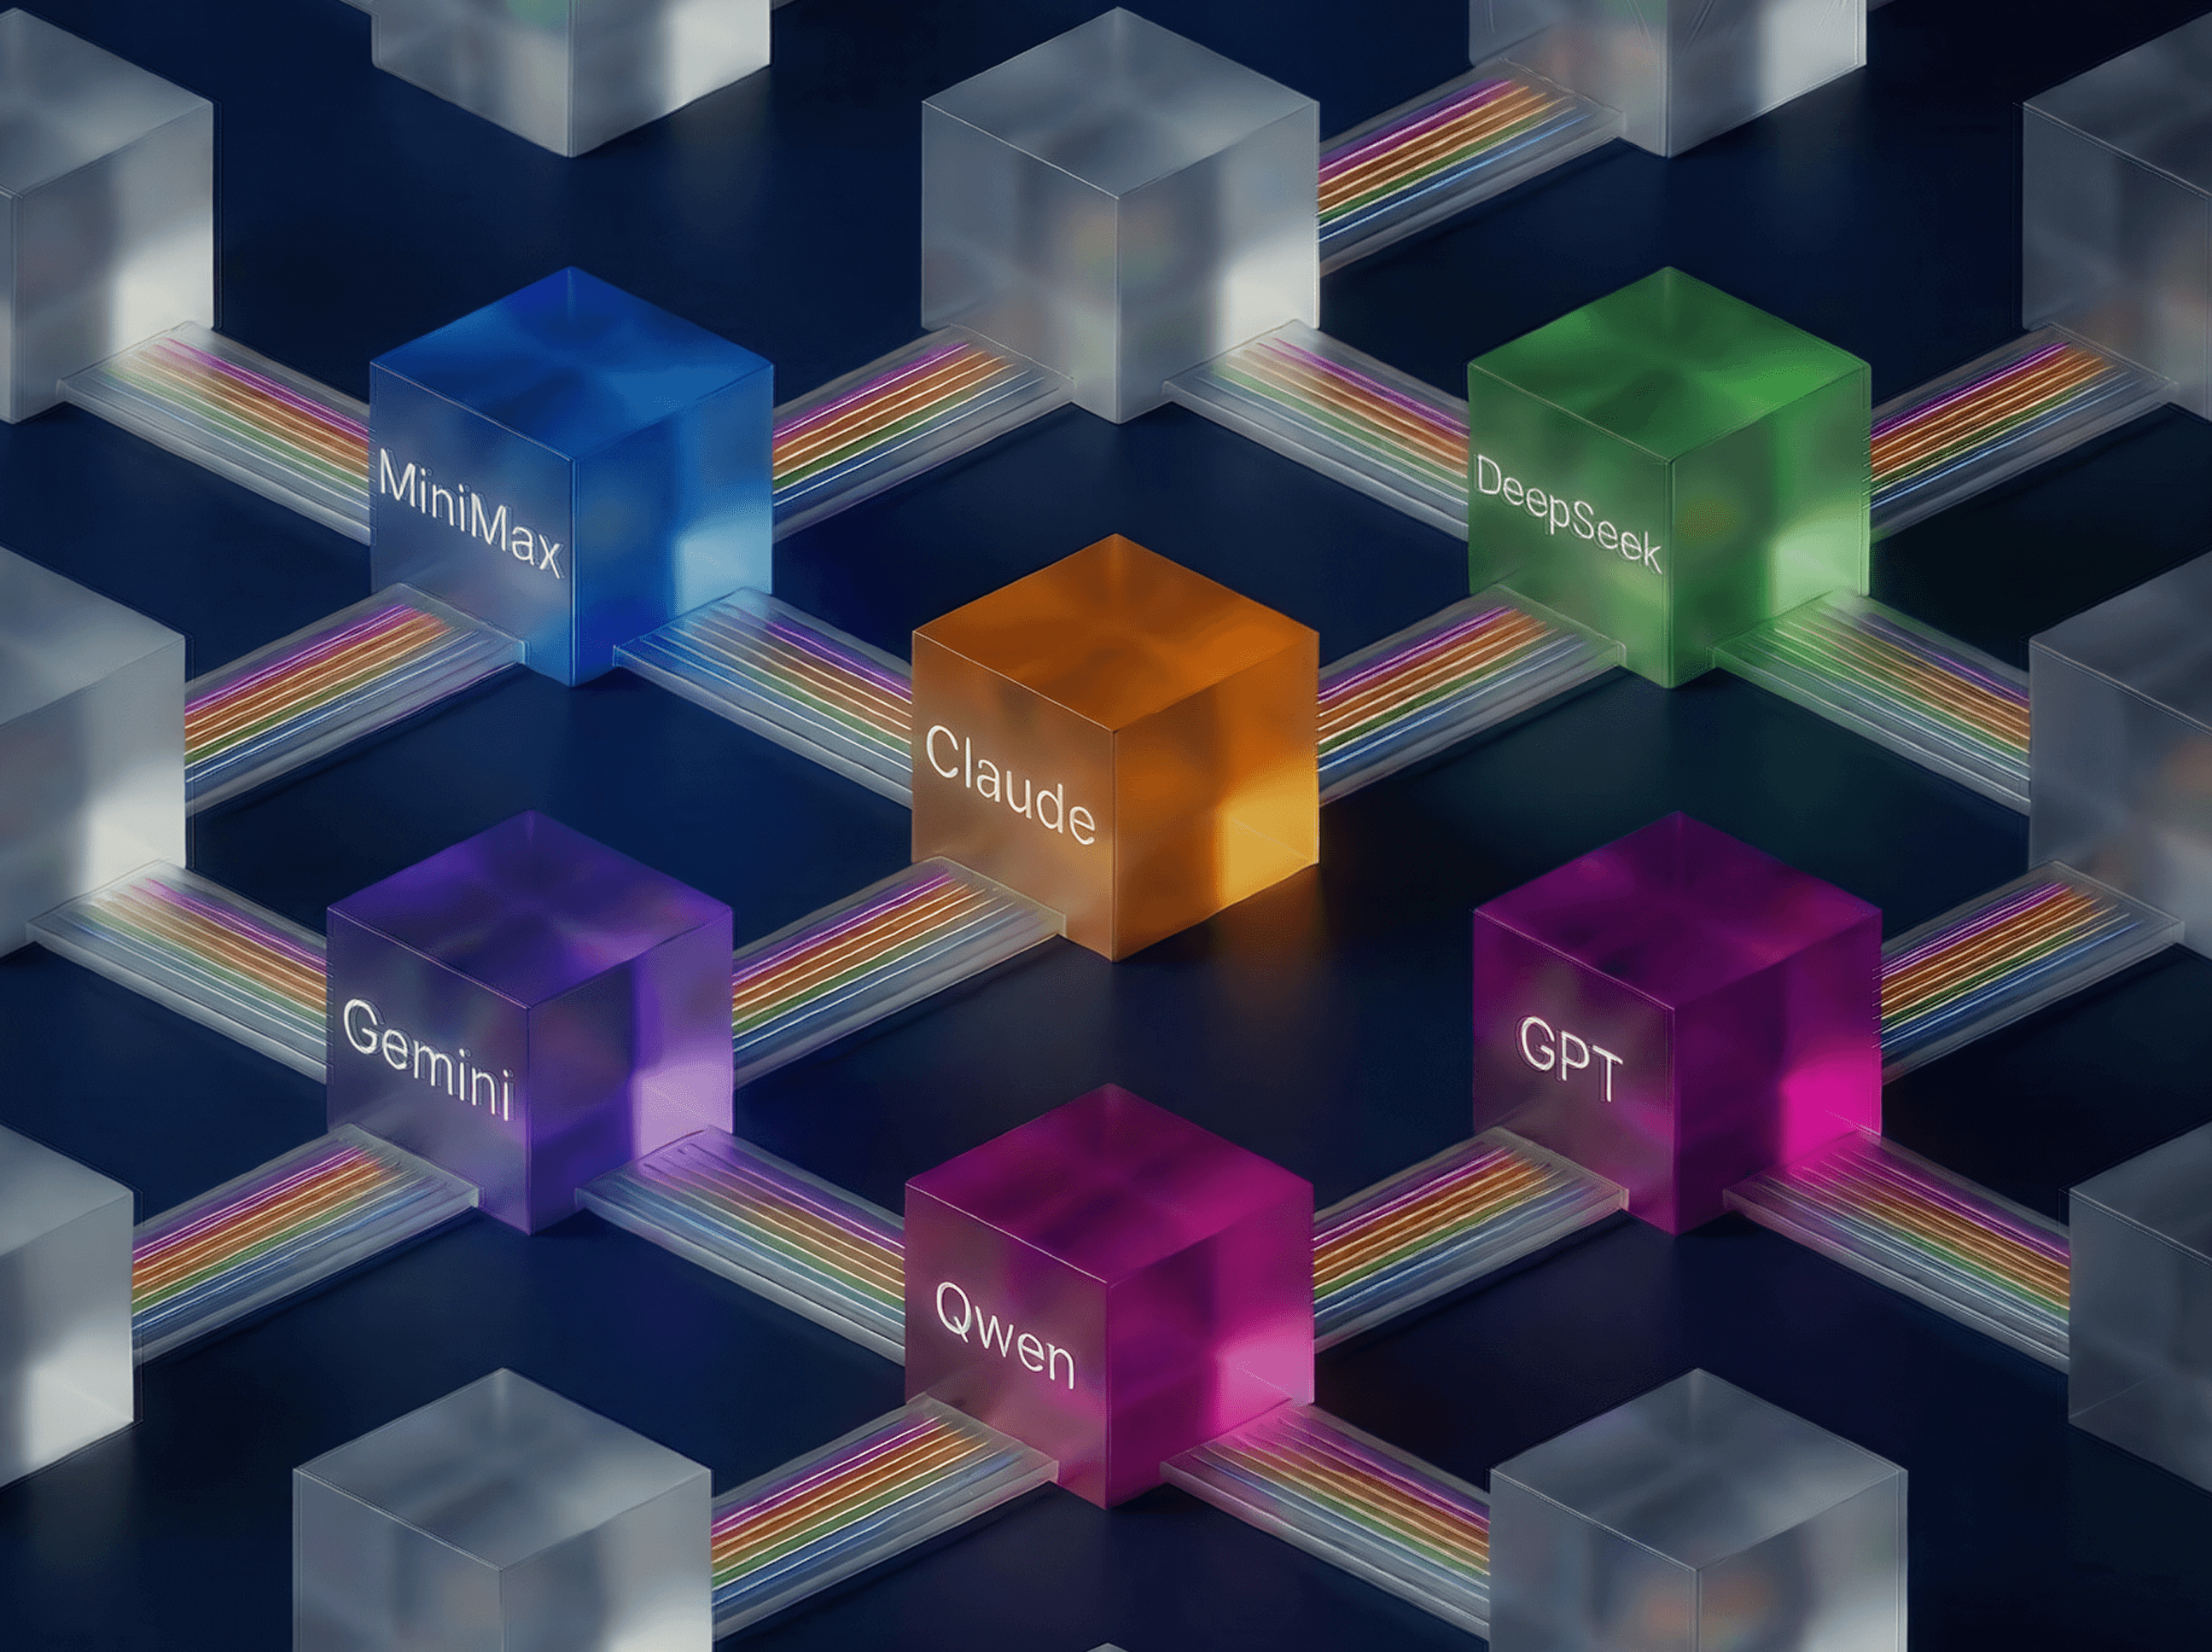
One API accesses global open-source & commercial LLMs
Updated: Oct 20, 2026
Claude Opus 5.5 is Anthropic's new-generation flagship model released in September 2026, officially positioned for "long-running agentic coding and knowledge work." It is the first model in the Claude 5.5 family, and it performs strongly across professional evaluations. Improved communication is a key focus of this upgrade. Anthropic says Opus 5.5's output is "more like a good colleague" — leading with information, reducing jargon, and following the writing rules users provide more strictly. Customer feedback supports this: one tester said design specification documents were nearly usable without modification, and the model's rewritten prompts were even preferred over the original author's own version. On safety, Anthropic says Opus 5.5 achieved its best results to date in automated behavior audits, covering nearly 2,000 simulated scenarios, with improvements in both resisting prompt injection and reducing hard-boundary breaches.
Text and vision reasoning model, an efficient member of Anthropic's Claude 5.5 family, designed to balance speed, intelligence, and cost efficiency. It supports text and image inputs, a 1M-token context window, up to 128K output, and adaptive thinking, with strong capabilities in coding, bug fixing, visual understanding, and creating polished documents, slides, and spreadsheets. Core Capabilities: Efficient Reasoning · Coding · Vision Understanding · Document Generation · Agent Tasks Use Cases: Software Development · Bug Fixing · Document Processing · Slides & Spreadsheets · Everyday Productivity
Text and vision multimodal reasoning model, OpenAI's next-generation flagship model built for demanding end-to-end work. It delivers state-of-the-art capabilities in computer use, software engineering, research, and professional workflows, enabling autonomous multi-step tasks such as browsing websites, operating software, writing and testing code, and creating documents, spreadsheets, and presentations. It supports a 1.05M-token context window and advanced tools including web search, code execution, and computer use.
Reasoning model with text and image input, GPT-6.1 Sol is a major upgrade to GPT-6 Sol, designed for complex coding, computer use, and professional work. It brings performance closer to GPT-6 Astra while maintaining Sol's cost-efficient pricing, with stronger agentic coding, computer use, professional task execution, and overall reasoning. It supports a 1.05M-token context window, 128K maximum output, multiple reasoning-effort levels, and extensive tool use, making it well suited to long-horizon agents and demanding professional workflows. Standard API pricing remains $2/M input and $10/M output, with cached input priced at just $0.10/M. Core Capabilities: Deep Reasoning · Agentic Coding · Computer Use · Software Engineering · Tool Use Use Cases: Software Development · Codebase Maintenance · Agentic Workflows · Professional Work · Complex Task Automation
Image generation and editing model, the high-quality variant of OpenAI's GPT Image 2.5 family, optimized for detailed creative work, precise editing, and professional visual workflows. It improves image detail, natural lighting, textures, reference-image fidelity, and consistency across iterative edits, making it well suited for advertising, product visuals, brand design, and precision image editing.
Native multimodal reasoning model, Google's flagship Gemini 4 model designed for complex software engineering, deep research, and enterprise-grade agent workflows. It supports text, image, video, audio, and PDF inputs with text output, featuring a 1M-token unified context window, long decoding capability, and adjustable thinking levels. Compared with the Gemini 3 generation, it delivers stronger complex coding, multi-step reasoning, scientific problem solving, visual understanding, and autonomous agent execution, with support for code execution, Computer Use, Function Calling, Search Grounding, and other tools. It is built for long-running, high-complexity professional workflows. Core Capabilities: Deep Reasoning · Agent Execution · Software Engineering · Multimodal Understanding · Tool Use Use Cases: Software Development · Scientific Research · Financial Analysis · Legal Work · Enterprise Agents
A multimodal reasoning model from Meta Superintelligence Labs, accepting text, images, video, audio, and PDF input, with text output. It supports a 1,048,576-token context window and is optimized for complex reasoning, software development, and long-horizon agent workflows. Compared with Muse Spark 1.2, it improves instruction following, long-horizon planning, and coding performance. Meta reports approximately 20% fewer tool calls and 25% fewer tokens in common coding workflows. Audio understanding is not yet fully supported. Core Capabilities: Multimodal Understanding · Advanced Reasoning · Coding and Debugging · Tool Calling · Long-Horizon Agent Execution Use Cases: Software Engineering · Large Codebase Analysis · Browser Automation · Enterprise Workflows · Multi-Step Agent Tasks
Reasoning model with text and image input, xAI's next-generation model designed for coding, agentic tasks, and knowledge work. It supports a 500K-token context window, multiple reasoning levels from low to xhigh, and built-in function calling, web search, X search, and code execution for sustained reasoning and verification across complex workflows. Core Capabilities: Advanced Reasoning · Coding · Agentic Tasks · Long Context · Tool Use Use Cases: Software Development · AI Agents · Deep Research · Professional Knowledge Work · Complex Task Automation
A text-generation large language model and Tencent Hunyuan's next-generation MoE flagship, featuring 770B total parameters with 49B active parameters and a 1M-token context window. Its key strengths include long-horizon coding, advanced reasoning, professional productivity, and scientific analysis, with strong performance on cross-file tasks, software engineering, data analysis, financial modeling, and game prototyping. It is well suited for AI agents, software engineering, enterprise productivity, research, and long-context workflows.
Reasoning model with text and image input, an upgraded version of DeepSeek V4.1 Flash optimized for efficient coding, end-to-end project development, and cost-effective agent execution. Compared with its predecessor, it improves benchmark performance and task completion speed while producing shorter outputs to reduce overall task costs. It delivers stronger performance in code development, repository-level changes, automation, and visual understanding, with a 1M-token context window and 384K maximum output. It is well suited to high-volume coding and complex agent workflows. Core Capabilities: Deep Reasoning · Agentic Coding · End-to-end Development · Visual Understanding · Efficient Tool Use Use Cases: Software Development · Codebase Maintenance · Game & 3D Project Generation · Workflow Automation · Multimodal Analysis
Qwen3.8 Max (Model ID: qwen3.8-max) is a flagship reasoning multimodal large language model released by Alibaba Qwen, previewed in July 2026 and officially launched in August 2026. Built on a Mixture-of-Experts (MoE) architecture with 2.4 trillion total parameters and approximately 95 billion active parameters per token, its key strengths include advanced reasoning, software engineering, agent execution, and multimodal understanding. The model supports text, image, and video inputs, features a 1M-token context window, and is designed for AI agents, software engineering, scientific research, enterprise AI, and other complex knowledge-intensive workloads. Alibaba also announced plans to release the model with open weights. Official benchmarks position it among the world’s leading frontier models.
Kimi K3 is an open-weight multimodal large language model released by Moonshot AI in July 2026. As the world's first open 3T-class model, its key strengths include a 1 million-token context window, native multimodal understanding, advanced agentic coding, and long-horizon knowledge work. Built on the new Kimi Delta Attention architecture, it delivers outstanding performance in software engineering, long-document analysis, complex reasoning, and automated workflows. It is ideal for AI agents, software development, research, enterprise knowledge management, and complex automation tasks.
Multi-Scenario Support
Focus on Building, Exploring & Creating
Turn AI Visions into Reality
AI Assistants
Optimizes workflows & agents. Powers smart CS, doc validation & deep data analysis
RAG
Retrieves KB data for precision. Delivers instant, reliable feedback for accurate outputs
Coding
Smart coding with inline correction & auto-complete. Guides syntax & structural compliance
Search
Retrieves linked data for precision. Delivers instant, reliable feedback
Content Generation
Multimodal creation (Text/Video). Auto-generates social copy & deep analysis reports
Agents
Logic planning & tool execution. Efficiently handles complex, multi-step workflows
Fits Every Scenario
Flexible Deployment
Reserved CU
Ensure stability. Transparent, controllable billing
Fine-tuning
Tailor high-perf models to needs. Auto one-click deployment
Serverless
Run any model via API. Pay-as-you-go costs
Elastic
Scalable inference & flexible deploy. Face traffic spikes easily
Smart API
Unified API, Integrated routing, throttling cost control
Built for Developers
Speed, Accuracy, Reliability & Value
No Compromises
Efficiency
High concurrency & low latency at competitive rates. Maximize your ROI
Speed
Optimized for LLMs. Experience lightning-fast inference
Control
Fine-tuning & deploy with ease. No infra hassles or stack lock-in
Flexibility
Serverless or Dedicated servers. Deploy the way fits best
Simplicity
One-API supports all models. Zero effort on integration
Privacy
Zero data storage, ever. Your data always under your control